iblai-vibe-agent-evalslisted
Install: claude install-skill iblai/vibe
# /iblai-vibe-agent-evals
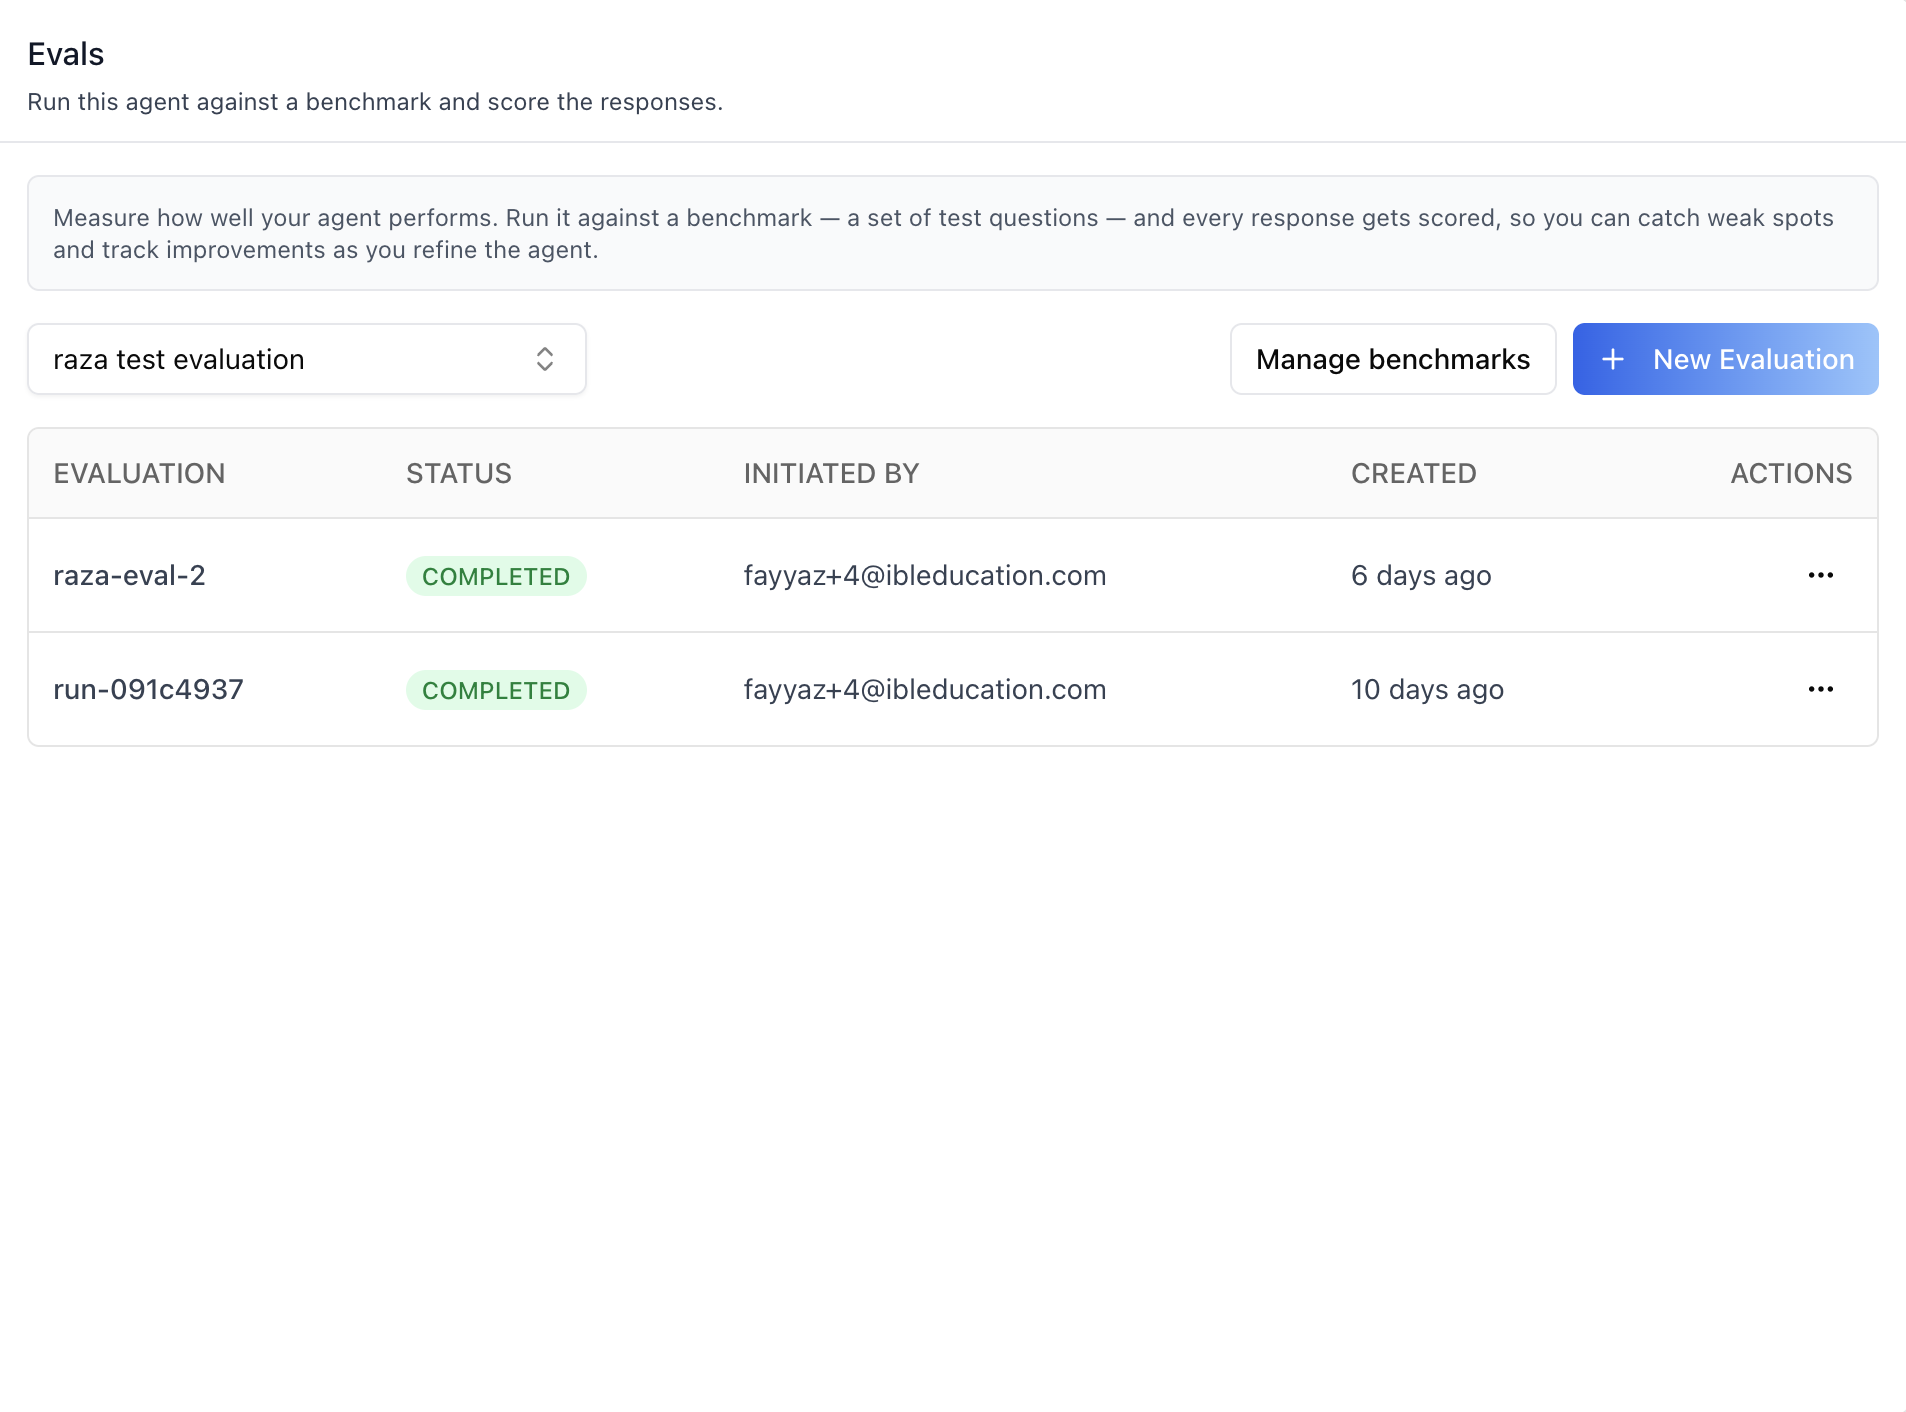
Add the agent **Evals tab** -- run your agent against a benchmark (a set
of test questions) and score every response, so you can catch weak spots
and track improvements as you refine the agent. The tab bundles several
surfaces into one component: a benchmark picker, an evaluations table
with status badges and a per-row actions menu (View results / New review /
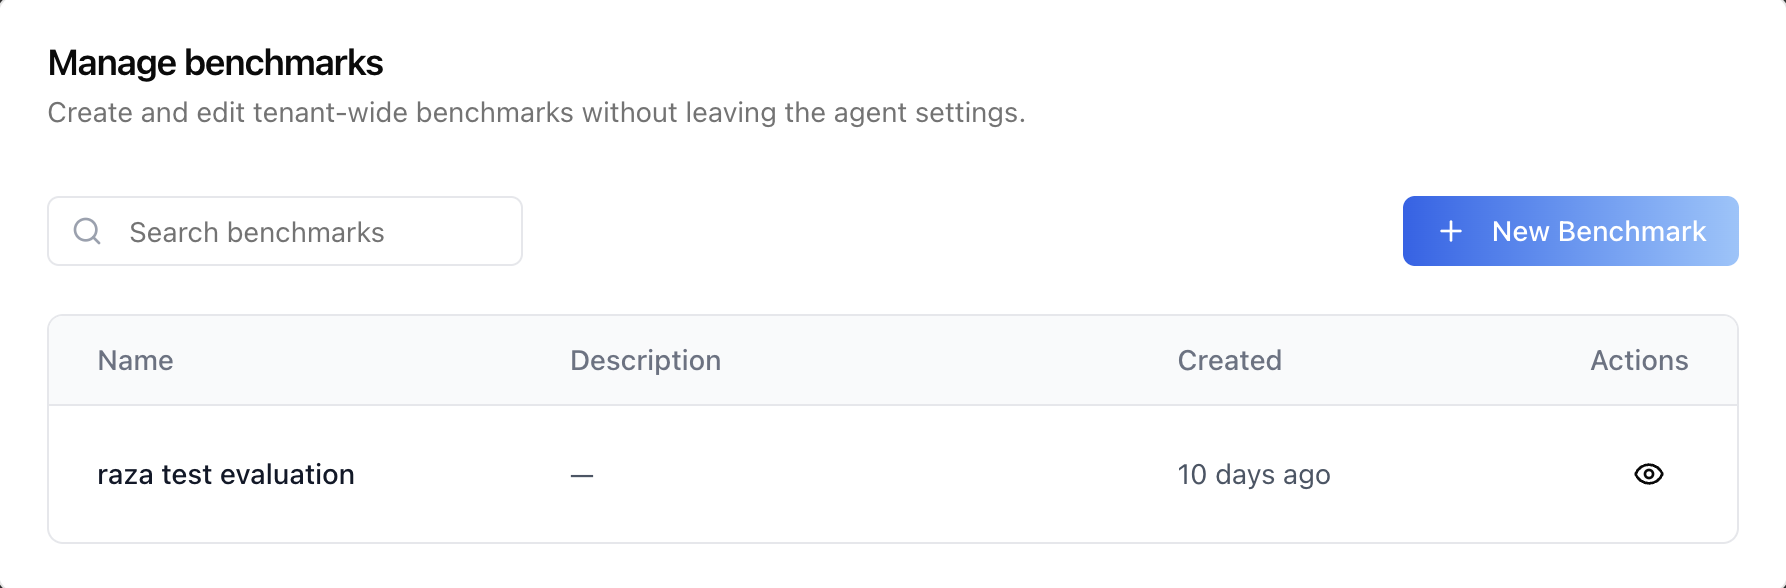
Check status / Export CSV / Delete), a **New Evaluation** dialog, an
embedded **Manage benchmarks** dialog (create benchmarks, add Q&A pairs
manually or via CSV upload), a results modal showing every trace with its
scores and LLM-as-Judge reviews, and an **Evaluate** (new review) modal
with an LLM provider/model picker. This is one tab in the wider
agent-settings family (`access`, `api`, `datasets`, `disclaimers`,
`embed`, `evals`, `history`, `llm`, `memory`, `prompts`, `safety`,
`settings`, `tasks`, `tools`). Each tab is a separate skill. All tabs
share the same `AgentSettingsProvider` wrapper -- set it up once and mount
as many tabs as you need.
![Results modal (traces, scores, reviews)](https://raw.githubusercontent.com/ib